

最新NCP-MCI-6.5合格保証試験問題集には正確で最新な問題があります
NCP-MCI-6.5試験ブレーン問題集で学習注釈と理論
質問 # 91
An administrator is reviewing performance of a core banking system that routinely has 20,000 concurrent users. During, business hours, the CPU on the applications servers runs at close to 100%. The administrator needs to determine if there is a performance issue specific to the app servers, the database servers, or all servers on the cluster.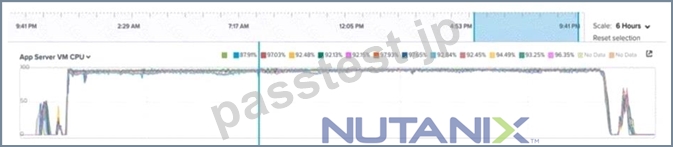
Which metrics should the administrator review in Prism Analysis Graphs?
- A. Cluster IO, Network, Database and App Server CPU
- B. Cluster CPU and Memory Only
- C. Cluster IO, CPU, Memory, Network, App Server CPU
- D. Cluster IO, CPU, Memory and Database and App Server CPU
正解:C
解説:
In this case, the administrator wants to investigate the performance of a core banking system that consists of application servers and database servers. The application servers have high CPU utilization during business hours, which may indicate a bottleneck or a resource contention issue. The administrator needs to review multiple metrics in Prism Analysis Graphs to identify the root cause and determine if there is a problem with the app servers only, or with other components as well.
The metrics that are relevant for this analysis are:
* Cluster IO: This metric shows the input/output operations per second (IOPS) and throughput (MBps) of the cluster. It can help to understand if there is a high demand for disk IO from the VMs or if there is any latency or congestion in the storage layer.
* Cluster CPU: This metric shows the CPU utilization (%) and load average of the cluster. It can help to understand if there is enough CPU capacity in the cluster to handle the workload or if there is any imbalance or contention among hosts.
* Cluster Memory: This metric shows the memory utilization (%) and available memory (GB) of the cluster. It can help to understand if there is enough memory capacity in the cluster to support the VMs or if there is any pressure or swapping in the memory layer.
* Network: This metric shows the network throughput (MBps) and packets per second (pps) of the cluster.
It can help to understand if there is enough network bandwidth in the cluster to transfer data between hosts and VMs or if there is any congestion or packet loss in the network layer.
* App Server CPU: This metric shows the CPU utilization (%) and load average of each application server VM. It can help to understand if thereis any variation or anomaly in the performance of each app server or if there is any correlation with other metrics.
* Database Server CPU: This metric shows the CPU utilization (%) and load average of each database server VM. It can help to understand if there is any variation or anomaly in the performance of each database server or if there is any correlation with other metrics.
質問 # 92
An administrator manages an AHV cluster that is dedicated to a dev/test environment. The administrator receiving complaints from users that they are unable to create new VMs on the cluster.
After the reviewing the cluster, the administrator finds that the memory resources are almost fully utilized, with many VMs over-provisioned on memory.
What option is the most efficient resolution to enable additional VMs to be created?
- A. Disable HA Reservation on the cluster.
- B. Enable Memory Overcommit on the over-provisioned VMs.
- C. Upgrade the nodes with additional memory DlMMs.
- D. Enable Memory HA on the over-provisioned VMs.
正解:B
解説:
Enable Memory Overcommit on the over-provisioned VMs is the most efficient resolution to enable additional VMs to be created. Memory overcommit allows VMs to use more memory than physically available on a host by compressing and swapping memory pages to storage1. This can improve memory utilization and increase VM density on a cluster1. However, memory overcommit is not supported when HA is configured to use reserved hosts, so you may need to disable HA reservation on the cluster before enabling memory overcommit
1.
質問 # 93
A VM in a 12-node Nutanix cluster is hosting an application that has specific Physical GPU requirements.
Only three nodes in the cluster meet this requirement.
The administrator wants to allow a general workload to be distributed across all nodes in the cluster and must make sure that the node hosting the VM meets its requirements.
How should the administrator perform this task?
- A. Configure anti-affinity rules between the application VM and the other VMs running on the cluster.
- B. Configure VM-Host affinity for the nodes that meet the application's GPU requirement.
- C. Create a sperate three-node cluster using the nodes that meet the requirement.
- D. Over-Provision the application VM with additional virtual GPUs.
正解:B
質問 # 94
What is the expected operation during node addition when the new node has a different AOS version?
- A. The addition fails and forces the administrator to image using standalone Foundation.
- B. The entire cluster is upgraded to the latest one-click release.
- C. The node is added and a separate upgrade operation must be performed.
- D. The node is automatically re-imaged using the software currently running in the cluster.
正解:D
解説:
The node is automatically re-imaged using the software currently running in the cluster. This is because Nutanix supports a feature called Auto Re-Image that allows adding nodes with different AOS versions to an existing cluster without manual intervention. The Auto Re-Image feature detects the AOS version mismatch and automatically downloads and installs the same AOS version as the cluster on the new node. This ensures that the cluster remains in a consistent state and avoids any compatibility issues.
質問 # 95
Which data savings technique utilizes stripes and parity calculation in a Nutanix cluster?
- A. Deduplication
- B. Compression
- C. Parity strip
- D. Erasure coding
正解:D
質問 # 96
An administrator wants to reduce the largest amount of alert emails received from Prism Central.
Which two settings should the administrator customize to meet this requirement? (Choose two)
- A. Skip empty digest email
- B. Every Single Alert
- C. Email Recipients
- D. Dally Digest
正解:C、D
解説:
According to the Nutanix Support & Insights website1, you can configure alert emails through Prism Central by enabling or disabling customer email notification for each alert. You can also modify or create custom alert policies for different entities and clusters23.
質問 # 97
A customer wants to isolate a group of VMs within their Nutanix environment for security reasons. The customer creates a VM with two NICs to act as a firewall and installs the appropriate software and certificates.
However, no one from the outside can access the application.
What is the likely cause of this problem?
- A. A shared volume group must be used by all isolated VMs
- B. More than one NIC cannot be added to a VM
- C. One of the NICs needs to be configured on the internal VLAN
- D. Wireshark is installed on the NAT VM
正解:C
質問 # 98
An administrator wants to replace and old node with a node of newer generation in a 3-node cluster. The administrator has already chosen the appropriate node. But unable to remove it from the cluster.
Why is the Remove Host option not shown in the exhibit?
- A. The host needs to be placed into maintenance Mode before.
- B. It is only possible to remove a host from a cluster using CLI.
- C. It is not possible to remove a host from a 3-node cluster.
- D. It is not possible to remove a node from a the cluster using Prism Central
正解:C
解説:
A Nutanix cluster requires a minimum of three nodes to maintain quorum and data availability. Removing a node from a 3-node cluster would violate the redundancy factor and cause data loss. Therefore, it is not possible to remove a host from a 3-node cluster using Prism or CLI. The only way to replace a node in a 3-node cluster is to use the Foundation tool, which will erase the existing cluster configuration and create a new cluster with the new node1.
質問 # 99
An administrator is adding a node with a higher AOS release to an existing cluster.
What is the most efficient action an administrator should take to ensure it is in a supported state?
- A. Perform standalone reimage of the new node and then add to cluster
- B. Add the node to the cluster and leave the existing AOS version in place
- C. Add the node to the cluster and reboot all running VMs to use new release
- D. Destroy cluster and foundation with the new node in place
正解:A
質問 # 100
Which two methods are available when migrating a VM from a legacy 3-tier solution using VMware ESXi to AHV? (Choose two.)
- A. Deploy the Move appliance.
- B. Import the .vmdk into the Image Service.
- C. Use shared nothing live migration.
- D. Use Cross-Hypervisor DR.
正解:A、D
質問 # 101
Refer to Exhibit:
An administrator needs to enable inline deduplication for a pre-existing storage container. When trying to enable deduplication on the storage container. this feature is grayed-out.
What is the reason for this behavior?
- A. The cluster has hybrid storage and deduplication is supported only on all-flash clusters.
- B. Replication Factor 1 is configured on the storage container.
- C. Capacity reservation is not enabled on the storage container.
- D. The cluster has less than 5 nodes which is the minimum node-count to enable deduplication.
正解:A
解説:
Nutanix supports two types of deduplication: post-process and inline. Post-process deduplication runs periodically on a schedule and can be enabled on any cluster. Inline deduplication runs in real time before data is written to disk and can be enabled only on all-flash clusters.
Therefore, by checking the type of storage and the type of deduplication, you can determine if you can enable inline deduplication on a storage container or not.
Nutanix inline deduplication is a feature that reduces the stored size and avoids duplicate data on a storage container1. It is recommended only on some specific scenarios, such as when using Nutanix Files or virtual desktop infrastructure (VDI) workloads12.
質問 # 102
After logging into Prism Element, an administrator presses the letter A on the Keyboard.
What is the expected outcome of this input?
- A. API Explorer page will launch
- B. About Nutanix page will launch
- C. Analysis will launch
- D. Alerts page will launch
正解:D
質問 # 103
A system administrator needs to add more VMs to their Nutanix cluster.
Which two actions should the administrator perform to determine if the current cluster can accommodate the new VMs? (Choose two)
- A. Perform an inventory with Life Cycle Management
- B. Utilize Optimize Resources for VM efficiency
- C. Determine utilization with Cluster Runway
- D. Enable Deduplication and Ensure Coding
正解:B、C
解説:
According to the web search results, the two actions that the administrator should perform to determine if the current cluster can accommodate the new VMs are:
Utilize Optimize Resources for VM efficiency: Optimize Resources is a feature in Prism Central that helps the administrator improve the efficiency and performance of their VMs by identifying and resolving issues such as overprovisioning, inactivity, constraints, or bullying3. By using Optimize Resources, the administrator can reclaim unused resources and optimize the resource allocation for their VMs3.
Determine utilization with Cluster Runway: Cluster Runway is a feature in Prism Central that helps the administrator estimate how long their cluster can continue to run normally based on the current consumption rate of CPU, memory, and storage resources4. By using Cluster Runway, the administrator can see how adding more VMs will affect the resource utilization and capacity of their cluster4.
質問 # 104
A customer has a 24-node cluster with all containers configured with RF3. Two different nodes have incurred a simultaneous HDD failure.
What is the result?
- A. The VMs with data on those drives crash, and an HA event occurs, restarting them on a remaining healthy node.
- B. Sixty minutes after the failures a rebuild of the lost data can remaining HDDs begins to restore to three replicas.
- C. The Nutanix cluster recognizes the failures and immediately begins to rebuild lost data to three replicas.
- D. The cluster runs in a degraded state until the failed drives are replaced and the data has been restored to three replicas.
正解:C
解説:
This is because Nutanix uses a distributed storage fabric (DSF) that replicates data across multiple nodes and drives to ensure data resiliency. When a drive fails, the cluster detects the failure and initiates a data rebuild process to restore the replication factor (RF) of the affected containers. The data rebuild process does not affect the availability or performance of the VMs, as they can still access their data from other replicas on other nodes or drives. Therefore, there is no need to wait for 60 minutes, use a shared volume group, or trigger an HA event.
質問 # 105
An administrator was reviewing various AOS logs when a it was noticed that the time of the logs were off by several hours.
Which initial step was missed during the post process cluster configuration?
- A. Setting the cluster time zone via CVM NCLI
- B. Setting the cluster time zone via PE GUI
- C. Setting the cluster time zone via CVM ACLI
- D. Setting the cluster time zone via PC GUI
正解:A
解説:
The cluster time zone is a setting that determines the time zone used by all CVMs in the cluster. The cluster time zone affects the timestamps of Nutanix logs, events, alerts, and reports. The cluster time zone also affects the scheduling of tasks such as snapshots, replication, and upgrades. By default, the cluster time zone is set to UTC (Coordinated Universal Time) when the cluster is created3.
To change the cluster time zone, the administrator needs to use the ncli (Nutanix command-line interface) on any CVM in the cluster. The steps are as follows4:
Log in to any CVM using SSH.
Run ncli cluster get-timezone to check the current cluster time zone.
Run ncli cluster set-timezone timezone=<timezone> to change the cluster time zone, where <timezone> is a valid time zone identifier (for example, America/New_York).
Run ncli cluster get-timezone again to verify that the cluster time zone has been changed.
Note that changing the cluster time zone does not affect the time zone of Prism Element or Prism Central VMs. To change their time zone, the administrator needs to use Prism Element UI or Prism Central UI respectively5.
質問 # 106
Refer to Exhibit:
An administrator is attempting to create an additional virtual switch on a newly deployed AHV cluster, using the two currently disconnected interfaces. The administrator is unable to select the disconnected interfaces when creating the virtual switch.
What is the likely cause of this issue?
- A. Interfaces must be assigned to virtual switches via the cli
- B. Only one interface is available on the selected hosts.
- C. Interfaces must be connected to the network before they can be assigned.
- D. The disconnected interfaces are currently assigned to virtual switch 0,
正解:D
解説:
when you create a new virtual switch on AHV, you need to select one or more uplink interfaces that are connected to a physical network. You cannot select an interface that is already assigned to another virtual switch. By default, AHV creates a virtual switch called br0 that uses all available interfaces on the host2. Therefore, if you want to use some of those interfaces for another virtual switch, you need to remove them from br0 first.
https://masteringnutanix.com/2020/06/13/how-to-create-an-ahv-virtual-switch-with-single-uplink/
質問 # 107
Refer to Exhibit:
An administrator is trying to create a custom alert policy for all VMs.
Why is the Alert warning if field greyed cut?
- A. The Enable Policy option checked.
- B. The Behavioral Anomaly threshold is set.
- C. The Auto resolve alerts option is checked.
- D. The Alert critical if threshold is set.
正解:B
解説:
when you create a custom alert policy, you can choose between two types of thresholds: Static Threshold and Behavioral Anomaly. Static Threshold allows you to set a fixed value for the metric that triggers the alert. Behavioral Anomaly allows you to use machine learning to detect abnormal behavior based on historical data.
If you select Behavioral Anomaly as the threshold type, you cannot set a warning level for the alert. You can only set a critical level that indicates how much deviation from normal behavior is considered an anomaly3. Therefore, the Alert warning if field is greyed out when you select Behavioral Anomaly.
質問 # 108
An administrator initially performed a cluster Foundation using a flat switch without any VLAN configuration.
After the Foundation, the administrator moved the dual 25Gb data ports and single 1Gb IPMI port to the actual switches with the below network configurations:
. All VLANs are tagged
. VLAN 1000 for CVM\Hypervisor traffic
VLAN 1001 for User VM traffic
. VLAN 100 for IPMI traffic
After moving the IPMI network links, the administrator can no longer ping the IPMI IPs.
Which two changes does the administrator need to make? (Choose two.)
- A. SSH to AHV and change the IP address using IPMI tool.
- B. SSH to AHV and set the VLAN ID using IPMI Tool.
- C. SSH to CVM and restart Genesis on all CVMs.
- D. SSH to CVM and restart network services on all host.
正解:A、B
解説:
The issue described pertains to the inability to ping the IPMI IPs after moving the IPMI network links to the actual switches with specific VLAN configurations. The two changes that the administrator needs to make are:
A: SSH to AHV and set the VLAN ID using IPMI Tool: Since all VLANs are tagged in the new network configuration, the IPMI network interface needs to be aware of the VLAN it's supposed to communicate on.
This can be achieved by setting the VLAN ID using the IPMI Tool on the AHV.
C: SSH to AHV and change the IP address using IPMI tool: If the IPMI IP addresses were initially set in a different subnet that is not routable in the new network configuration, the administrator would need to change the IPMI IP addresses to match the new network configuration. This can be done by SSHing to the AHV and using the IPMI Tool to change the IP address.
質問 # 109
Refer to Exhibit:
After configuring modules for a Remote Syslog Server, the settings are as shown. The administrator notices that even though the level parameter is set to EMERGENCY, that all monitor logs are being sent.
What is the likely cause of this issue?
- A. Having the Module Name set to STARGATE sends all monitor logs regardless of the level.
- B. A Log Level of EMERGENCY includes all monitor logs.
- C. A second rsyslog server is configured to send all monitor logs.
- D. The true setting for Include Monitor Logs sends all monitor logs regardless of the level.
正解:B
質問 # 110
......
合格させるNutanix NCP-MCI-6.5テスト練習問題 試験問題集:https://www.passtest.jp/Nutanix/NCP-MCI-6.5-shiken.html
ベストNutanix Certified Professional学習ガイドにはNCP-MCI-6.5試験問題集:https://drive.google.com/open?id=1FZtIQ2Gs5yJLHyZmZWojO7HGZtFi7jAb