

Nutanix NCP-MCI-6.5豪華セット学習ガイドにはオンライン試験エンジン
NCP-MCI-6.5問題集レビュー専門クイズ学習材料
Nutanix NCP-MCI-6.5認定試験は、Nutanix Solutionsを扱い、MulticLoudインフラストラクチャの専門知識を実証したいITプロフェッショナルにとって貴重な資格です。業界の熟練したIT専門家に対する需要の増加に伴い、この認定を取得することで、競争の激しい雇用市場で個人が際立ってキャリアを促進するのに役立ちます。
Nutanix Certified Professional - Multicloud Infrastructure (NCP-MCI) v6.5 認定試験は、Nutanix テクノロジーのソリューションを管理および展開する能力と知識を検証したい IT プロフェッショナル向けに設計されています。この認定試験は、クラウドコンピューティング、仮想化、ストレージ管理に関連する主要なコンセプトとともに、Nutanix インフラストラクチャを管理、トラブルシューティング、最適化する能力を評価します。この試験に合格することで、現代のマルチクラウドインフラストラクチャ展開をサポートするために Nutanix テクノロジーを使用する候補者の熟練度が証明されます。
認定試験は、ITインフラ、仮想化、ネットワークの経験がある個人を対象としています。試験は、Nutanixテクノロジーを使用して、ハイブリッドおよびパブリッククラウド環境を含むマルチクラウドインフラストラクチャソリューションを展開および管理する能力をテストするように設計されています。
質問 # 105
Refer to Exhibit: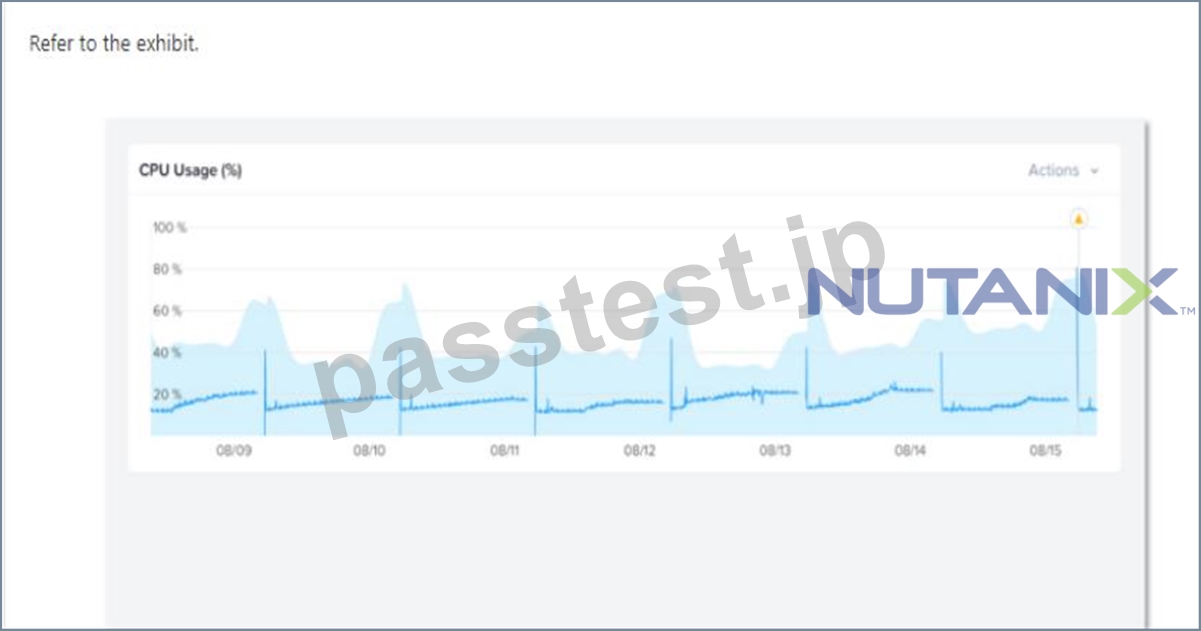
Why has an anomaly been triggered?
- A. Because the CPU usage dropped belon' 20%
- B. Because the blue band range increased over the last 2 days
- C. Because the CPU usage reached 100%
- D. Because the CPU usage crossed the blue band.
正解:D
解説:
Nutanix leverages a method for determining the bands called 'Generalized Extreme Studentized Deviate Test'. A simple way to think about this is similar to a confidence interval where the values are between the lower and upper limits established by the algorithm.
Another web source3 shows an example of how anomaly detection works in Nutanix Prism Central. In the video, you can see that when the observed value of a metric deviates significantly from the predicted value based on historical data, an anomaly event is triggered and displayed on a chart.
Therefore, by comparing the observed values with the predicted values based on historical data, Nutanix anomaly detection can identify abnormal behavior and alert you accordingly.
質問 # 106
How many Prism Central instances are required to deploy Leap:'
- A. One per availability zone
- B. One per physical site
- C. One per AHV cluster
- D. One per customer environment
正解:A
質問 # 107
An administrator needs to provide access for a user to view real-time performance metric for all VMs on all clusters across the datacenter.
Which method accomplishes this with the least effort and ongoing maintenance?
- A. Configure AD authentication create a custom role, assign the user to the role, and apply the role to all clusters and VMs
- B. Configure IDP authentication and assign the user to the Cluster Admin role in Prism Central.
- C. Configure AD authentication and assign the user to the Viewer role in Prism Element.
正解:A
解説:
The best method to provide access for a user to view real-time performance metrics for all VMs on all clusters across the datacenter is to configure AD authentication create a custom role, assign the user to the role, and apply the role to all clusters and VMs. This method accomplishes this with the least effort and ongoing maintenance because:
* AD authentication allows Nutanix Prism Central to integrate with an existing Active Directory (AD) domain and use AD users and groups for authentication and authorization5. This simplifies user management and avoids creating local users on Prism Central.
* Creating a custom role allows Nutanix Prism Central to define granular permissions for different actions and entities based on specific needs6. This ensures that users only have access to what they need and nothing more.
* Assigning the user to the custom role allows Nutanix Prism Central to grant access rights for that user based on the role definition7. This avoids assigning permissions individually for each user.
* Applying the role to all clusters and VMs allows Nutanix Prism Central to propagate the access rights for that role across all entities in scope8. This ensures that users can view real-time performance metrics for all VMs on all clusters without having to configure each entity separately.
References: 1: Health Dashboard - Prism Element Guide 2: Understanding Native VLANs - Cisco 3: VMs may lose network connectivity if connected to virtual network with ... - Nutanix Support & Insights 4: VLAN Configuration - AHV Networking Guide 5: Active Directory Authentication - Prism Central Guide 6: Create Custom Roles - Prism Central Guide 7: Assign Roles - Prism Central Guide 8: Apply Roles - Prism Central Guide
質問 # 108
Which method can be used to migrate a VM configured for UEFI-boot from a Nutanix Hyper-V cluster to AHV?
- A. Nutanix Move
- B. Storage vMotion
- C. Cloud Connect
- D. Live Migration
正解:A
解説:
Nutanix Move is a tool that allows you to migrate VMs from different sources to Nutanix AHV with minimal downtime and complexity. Nutanix Move supports migration from Hyper-V to AHV, including VMs configured for UEFI-boot. UEFI stands for Unified Extensible Firmware Interface, which is a standard for the software interface between the operating system and the firmware. UEFI-boot is a mode of booting that uses UEFI instead of BIOS (Basic Input/Output System) to load the operating system. UEFI-boot offers some advantages over BIOS-boot, such as faster boot time, larger disk support, and better security features1.
To migrate a VM configured for UEFI-boot from a Nutanix Hyper-V cluster to AHV, you need to use Nutanix Move and follow these steps2:
Download and deploy the Nutanix Move appliance on the AHV cluster.
Log in to the Nutanix Move web console and add the source Hyper-V environment and the target AHV environment.
Create a migration plan and select the VMs that you want to migrate. You can choose either automatic or manual preparation mode for the migration.
Start the migration plan and monitor the progress. The migration plan will perform data seeding, which is the process of copying the VM data from the source to the target in the background.
When the data seeding is complete, perform a cutover, which is the process of shutting down the source VMs and powering on the target VMs. The cutover will also configure the boot device for the UEFI-boot VMs on AHV.
Verify that the migrated VMs are working as expected on AHV.
References: 1: UEFI Boot - Nutanix Support & Insights 2: Hyper-V to AHV and Hyper-V to Nutanix Clusters on AWS VM Migration - Nutanix Support & Insights
質問 # 109
What is the expected behavior of the VMs residing on that host when a controller VM becomes unavailable?
- A. VM High Availability will restart the impacted VMs on another host
- B. The host will automatically redirect I/O and VMs will continue running.
- C. A Live Migration will be performed on the affected VMs.
- D. The impacted host and VMs will automatically shut down.
正解:B
解説:
According to the Nutanix Support & Insights web search result1, if the owner Controller VM becomes unavailable, the address moves to another Controller VM, ensuring that it is always available. This IP address is also used as a cluster-wide address by clients configured as part of Nutanix Files and other products.
Therefore, the host will automatically redirect I/O and VMs will continue running without any interruption.
質問 # 110
Refer to Exhibit.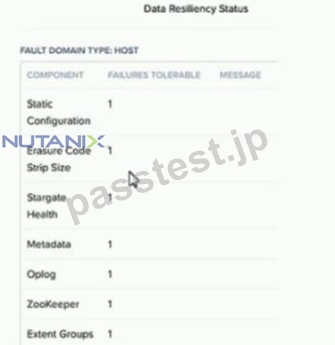
An administrator increases the cluster RF to 3. The containers are not modified.
What will the new values in the data resiliency dashboard be for FAILURES TOLERABLE for the Zookeeper and Extent Groups components?
- A. Zookeeper = 1 and Extent Groups = 2
- B. Zookeeper = 1 and Extent Groups = 1
- C. Zookeeper = 2 and Extent Groups = 1
- D. Zookeeper = 2 and Extent Groups = 2
正解:C
質問 # 111
What is the minimum time a newly created Deduplication storage policy takes to apply to the VMs in the container?
- A. 10 minutes
- B. 30 minutes
- C. 60 minutes
- D. 5 Minutes
正解:C
解説:
Deduplication is a feature that reduces space usage by consolidating duplicate data blocks on Nutanix storage.
Deduplication can be enabled on a storage container for either cache or capacity, or both. Cache deduplication is performed on the data in memory and SSD, while capacity deduplication is performed on the data in HDD. Capacity deduplication is not enabled by default and is available if you have purchased a Pro or higher license2. When you enable capacity deduplication on a storage container, it takes effect after 60 minutes3.
This delay allows the system to identify the best candidates for deduplication and avoid unnecessary overhead.
質問 # 112
An administrator has been asked to enable block awareness and increase the fault tolerance to FT2 on a Nutanix AHV cluster with the following configuration:
Four blocks
One node per block
Will the administrator be able to accomplish these tasks?
- A. Yes-FT2 requires a minimum of three nodes.
- B. No-Fault tolerance changes are not supported.
- C. No-FT2 requires a minimum of five nodes.
- D. Yes-Block awareness requires a minimum of three blocks.
正解:C
解説:
Fault tolerance (FT) is the ability of a cluster to withstand node failures and maintain data availability. FT is determined by the replication factor (RF) of the data, which is the number of copies of each data block stored on different nodes. FT = RF - 1, meaning that the cluster can tolerate as many node failures as one less than the RF. Block awareness is a feature that enhances fault tolerance by ensuring that data copies are distributed across different blocks, which are groups of nodes that share a power source and network switch. Block awareness requires a minimum of three blocks and a minimum of six nodes in the cluster.
In this scenario, the administrator has been asked to enable block awareness and increase the fault tolerance to FT2 on a Nutanix AHV cluster with the following configuration: Four blocks, One node per block. The administrator will not be able to accomplish these tasks because:
To enable block awareness, the cluster needs at least six nodes, but it only has four nodes.
To increase the fault tolerance to FT2, the cluster needs at least five nodes per RF3 or seven nodes per RF4, but it only has four nodes.
Therefore, the administrator will need to add more nodes to the cluster before enabling block awareness and increasing the fault tolerance to FT2.
質問 # 113
An administrator logs into the Nutanix Support Portal and notices there is a new version of the LCM Framework available. In an effort ensure LCM is providing the latest features, the administrator would like to upgrade LCM.
How can the LCM Framework be upgraded?
- A. Perform an LCM inventory
- B. Upload the latest LCM Framework bundle via Upgrade Software in Prism
- C. Upload the latest LCM Framework as an image in the image Configuration in Prism
- D. Upgrade AOS
正解:A
質問 # 114
An administrator is performing validation testing of a new-deploy cluster. During this test, the administrator disconnect each LAN interface from each of the nodes while pinging the hypervisor and guest VMs.
When the first interface is disconnected, pings continue as expected to the hypervisor, but pings stop responding from the guest. Pings continue when the interface is reconnected. When the second interface is disconnected, pings continue to both the hypervisor and guest VMs.
What could be the cause of this error?
- A. Switch ports are configured with different VLANs
- B. One of the network interfaces has a bad patch cable.
- C. Portfast is not enabled on the switch ports
- D. This is normal behavior for a LAN Failover
正解:A
質問 # 115
After running an LCM inventory it is noticed that there are a number of firmware and software updates available. The administrator would like to avoid any host reboots, but would like to apply some of the available updates?
- A. Data Drives
- B. AOS
- C. AHV
- D. M.2 Drives
正解:B、C
解説:
Explanation
AHV is the Acropolis Hypervisor that is used to run Nutanix clusters, and firmware and software updates can be applied to it without requiring any host reboots. AOS is the Acropolis Operating System that includes the hypervisor, storage and management components of the Nutanix cluster, and firmware and software updates can also be applied to it without requiring any host reboots.
質問 # 116
Refer to the exhibit.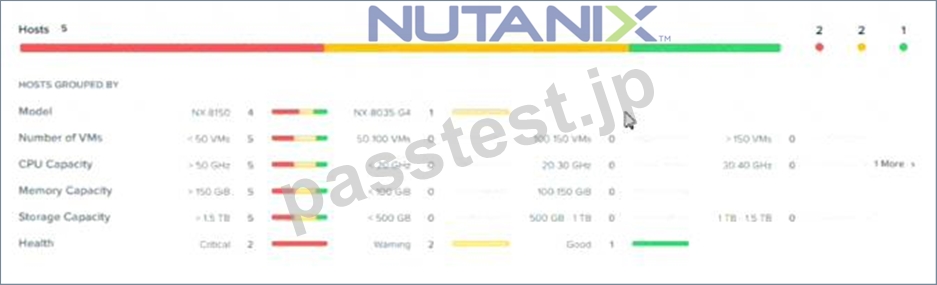
System Non-Root Partition Usage shows a warning or critical alert The administrator needs to change the frequency of checks and alerts to respond more quickly.
Where in Prism Element should the administrator change the frequency of checks and alerts?
- A. Health Dashboard > Manage Crocks > Frequency
- B. Alerts Dashboard > Manage Checks > Frequency
- C. Alerts Dashboard > Manage Checks > Schedule
- D. Health Dashboard > Manage Checks > Schedule
正解:B
質問 # 117
The administrator wants a container to be displayed and limited to 1TB in the hypervisor.
What advanced container setting must the administrator set?
- A. Advertised Capacity
- B. Advertised Quota
- C. Reserved Capacity
- D. Reserved Quota
正解:A
解説:
According to the Nutanix Support & Insights web search result3, advertised capacity is an advanced container setting that allows the administrator to reserve an advertised storage space for a storage container. An advertised capacity setting gives the hypervisor a maximum storage size that the storage container can use. This setting can be any arbitrary value greater than or equal to the resiliency required. The hypervisor ensures that the storage container storage doesn't go beyond the advertised capacity. If the administrator wants a container to be displayed and limited to 1TB in the hypervisor, they should set the advertised capacity to 1TB.
質問 # 118
An administrator is reviewing performance of a core banking system that routinely has 20,000 concurrent users. During, business hours, the CPU on the applications servers runs at close to 100%. The administrator needs to determine if there is a performance issue specific to the app servers, the database servers, or all servers on the cluster.
Which metrics should the administrator review in Prism Analysis Graphs?
- A. Cluster IO, Network, Database and App Server CPU
- B. Cluster IO, CPU, Memory, Network, App Server CPU
- C. Cluster IO, CPU, Memory and Database and App Server CPU
- D. Cluster CPU and Memory Only
正解:B
解説:
In this case, the administrator wants to investigate the performance of a core banking system that consists of application servers and database servers. The application servers have high CPU utilization during business hours, which may indicate a bottleneck or a resource contention issue. The administrator needs to review multiple metrics in Prism Analysis Graphs to identify the root cause and determine if there is a problem with the app servers only, or with other components as well.
The metrics that are relevant for this analysis are:
Cluster IO: This metric shows the input/output operations per second (IOPS) and throughput (MBps) of the cluster. It can help to understand if there is a high demand for disk IO from the VMs or if there is any latency or congestion in the storage layer.
Cluster CPU: This metric shows the CPU utilization (%) and load average of the cluster. It can help to understand if there is enough CPU capacity in the cluster to handle the workload or if there is any imbalance or contention among hosts.
Cluster Memory: This metric shows the memory utilization (%) and available memory (GB) of the cluster. It can help to understand if there is enough memory capacity in the cluster to support the VMs or if there is any pressure or swapping in the memory layer.
Network: This metric shows the network throughput (MBps) and packets per second (pps) of the cluster. It can help to understand if there is enough network bandwidth in the cluster to transfer data between hosts and VMs or if there is any congestion or packet loss in the network layer.
App Server CPU: This metric shows the CPU utilization (%) and load average of each application server VM. It can help to understand if there is any variation or anomaly in the performance of each app server or if there is any correlation with other metrics.
Database Server CPU: This metric shows the CPU utilization (%) and load average of each database server VM. It can help to understand if there is any variation or anomaly in the performance of each database server or if there is any correlation with other metrics.
質問 # 119
Refer to the exhibit.
Which two initial cluster configuration tasks were missed during the deployment process? (Choose two.)
- A. BIOS password changes
- B. Password policy changes
- C. CVM password changes
- D. Host password changes
正解:C、D
解説:
According to the image description, the exhibit shows a screenshot of a computer screen with a table of data.
The table has 6 columns and 4 rows. The columns are labeled "Date", "Time", "Status", "Details",
"Configuration", and "Duration". The rows contain information about different configurations and their statuses. The background is a light blue color. There is a pop-up message on the bottom right corner of the screen that reads "This question has been answered. Click here to enable the edit button." Based on the table data, it seems that the screenshot is taken from the Prism Central web console, showing the results of a cluster health check report. The report shows that there are four failed checks: Host Password Policy, CVM Password Policy, NTP Configuration, and Cluster Time Skew2. These checks indicate that some initial cluster configuration tasks were missed during the deployment process.
The Host Password Policy check verifies that the host passwords are not set to default values and are compliant with the password policy defined in Prism Central3. The CVM Password Policy check verifies that the CVM passwords are not set to default values and are compliant with the password policy defined in Prism Central4. These checks are important for ensuring the security and compliance of the cluster. Therefore, changing the host and CVM passwords from their default values and following the password policy guidelines are two initial cluster configuration tasks that were missed.
References: 1: VM Details View - Nutanix Support & Insights 2: Cluster Health - Nutanix Support & Insights 3: Host Password Policy - Nutanix Support & Insights 4: CVM Password Policy - Nutanix Support & Insights
質問 # 120
An administrator logs in to Prism Element goes to the Network view, and sees the output shown in the exhibit.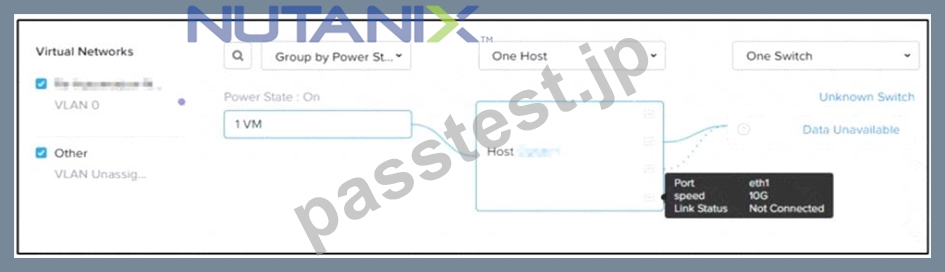
Which three steps must the administrator take to increase throughput to the host? (Choose three.)
- A. Connect the 10Gb interfaces to the physical switch.
- B. Change the VLAN ID to a higher priority ID.
- C. Remove any 1Gb interfaces still connected from the default bond.
- D. Change the bond mode to balance-slb or balance-tcp.
- E. Add a new switch to the network and connect 1Gb interfaces to it.
正解:A、C、D
解説:
These are the three steps that the administrator must take to increase throughput to the host. According to the network diagram, the host has two 10Gb interfaces and two 1Gb interfaces in the default bond, but only one of the 10Gb interfaces is connected to a switch. The other 10Gb interface is disconnected and has a red "X" on it.
The two 1Gb interfaces are also disconnected and have dotted lines. This means that the host is using only one
10Gb interface for all its network traffic, which limits its maximum bandwidth to 10 Gbps.
To increase the throughput, the administrator should connect both 10Gb interfaces to the physical switch, preferably to different switches for redundancy and high availability. This will allow the host to use both 10Gb interfaces for network traffic, which can increase its maximum bandwidth to 20 Gbps. However, this also requires changing the bond mode from active-backup to balance-slb or balance-tcp, which are load balancing modes that distribute network traffic across multiple interfaces based on source MAC address or TCP session1. The default bond mode of active-backup only uses one interface at a time and switches to another interface only when the active one fails2.
Finally, the administrator should remove any 1Gb interfaces still connected from the default bond, as they are not needed and may cause performance issues or conflicts with the load balancing modes. The 1Gb interfaces can be used for other purposes, such as management or backup networks, by creating separate bonds or bridges for them3. Alternatively, they can be left disconnected if they are not required.
質問 # 121
A configuration is single domain, single forest, and does not use SSL.
Which port number should be used to configure LDAP?
- A. 0
- B. 1
- C. 2
- D. 3
正解:D
解説:
Port 389 is the default port for LDAP without SSL encryption. Port 636 is used for LDAP over SSL (LDAPS). Port 3268 and 3269 are used for Global Catalog (GC) and Global Catalog over SSL (GCSSL), respectively2.
質問 # 122
An administrator manages a cluster and notices several failed components shown in the exhibit.
What two options does the administrator have to run all NCC checks manually? (Choose two.)
- A. Running ncc health_checks run-alll on the CVM
- B. Using the Actions drop-down menu in the Health dashboard of Prism Element.
- C. Using the action action drop-down menu in the Health dashboard of Prism Central
- D. Running noc health_checks run_all on the PC VM
正解:A、B
質問 # 123
An administrator wants to create a trunked interface on a VM on AOS 5.15x.
Which two steps should the administrator take first to achieve this? (Choose two)
- A. Use acli
- B. Update VM dialog.
- C. Log in over PE web UI.
- D. SSH to CVM.
正解:A、D
解説:
Explanation/Reference:
Reference:
#sthash.3uIAHeXZ.dpbs
質問 # 124
Refer to Exhibit:
An administrator wants to replace and old node with a node of newer generation in a 3-node cluster. The administrator has already chosen the appropriate node. But unable to remove it from the cluster.
Why is the Remove Host option not shown in the exhibit?
- A. It is not possible to remove a host from a 3-node cluster.
- B. It is only possible to remove a host from a cluster using CLI.
- C. It is not possible to remove a node from a the cluster using Prism Central
- D. The host needs to be placed into maintenance Mode before.
正解:A
解説:
A Nutanix cluster requires a minimum of three nodes to maintain quorum and data availability. Removing a node from a 3-node cluster would violate the redundancy factor and cause data loss. Therefore, it is not possible to remove a host from a 3-node cluster using Prism or CLI. The only way to replace a node in a
3-node cluster is to use the Foundation tool, which will erase the existing cluster configuration and create a new cluster with the new node1.
質問 # 125
......
試験問題解答ブレーン問題集でNCP-MCI-6.5試験問題集PDF問題:https://www.passtest.jp/Nutanix/NCP-MCI-6.5-shiken.html
NCP-MCI-6.5テスト準備トレーニング練習試験問題練習テスト:https://drive.google.com/open?id=1FZtIQ2Gs5yJLHyZmZWojO7HGZtFi7jAb