

信頼できるGoogle Cloud Certified Professional-Machine-Learning-Engineer問題集PDF 2024年01月03日最近更新された問題
必ず合格できるGoogle Professional-Machine-Learning-Engineer試験正確な150問題と解答あります
Google Professional Machine Learning Engineer Examは、機械学習の分野での個人の専門知識をテストするように設計されています。この認定は、Google Cloud Technologiesを使用して洗練された機械学習モデルを開発および展開する機能だけでなく、機械学習の概念とツールの強力な基盤を提供します。この試験では、Googleの機械学習ツールとサービスを使用して、堅牢でスケーラブルで効率的な機械学習モデルを構築および展開する能力を評価します。
質問 # 42
You work for a gaming company that has millions of customers around the world. All games offer a chat feature that allows players to communicate with each other in real time. Messages can be typed in more than 20 languages and are translated in real time using the Cloud Translation API. You have been asked to build an ML system to moderate the chat in real time while assuring that the performance is uniform across the various languages and without changing the serving infrastructure.
You trained your first model using an in-house word2vec model for embedding the chat messages translated by the Cloud Translation API. However, the model has significant differences in performance across the different languages. How should you improve it?
- A. Replace the in-house word2vec with GPT-3 or T5.
- B. Remove moderation for languages for which the false positive rate is too high.
- C. Train a classifier using the chat messages in their original language.
- D. Add a regularization term such as the Min-Diff algorithm to the loss function.
正解:B
質問 # 43
You recently joined an enterprise-scale company that has thousands of datasets. You know that there are accurate descriptions for each table in BigQuery, and you are searching for the proper BigQuery table to use for a model you are building on AI Platform. How should you find the data that you need?
- A. Execute a query in BigQuery to retrieve all the existing table names in your project using the INFORMATION_SCHEMA metadata tables that are native to BigQuery. Use the result o find the table that you need.
- B. Tag each of your model and version resources on AI Platform with the name of the BigQuery table that was used for training.
- C. Maintain a lookup table in BigQuery that maps the table descriptions to the table ID. Query the lookup table to find the correct table ID for the data that you need.
- D. Use Data Catalog to search the BigQuery datasets by using keywords in the table description.
正解:B
質問 # 44
You have trained a deep neural network model on Google Cloud. The model has low loss on the training data, but is performing worse on the validation dat a. You want the model to be resilient to overfitting. Which strategy should you use when retraining the model?
- A. Run a hyperparameter tuning job on Al Platform to optimize for the learning rate, and increase the number of neurons by a factor of 2.
- B. Run a hyperparameter tuning job on Al Platform to optimize for the L2 regularization and dropout parameters
- C. Apply a L2 regularization parameter of 0.4, and decrease the learning rate by a factor of 10.
- D. Apply a dropout parameter of 0 2, and decrease the learning rate by a factor of 10
正解:C
解説:
Applying a L2 regularization parameter of 0.4 and decreasing the learning rate by a factor of 10 can help to reduce overfitting and make the model more resilient. Source: Google Cloud
質問 # 45
You are developing models to classify customer support emails. You created models with TensorFlow Estimators using small datasets on your on-premises system, but you now need to train the models using large datasets to ensure high performance. You will port your models to Google Cloud and want to minimize code refactoring and infrastructure overhead for easier migration from on-prem to cloud. What should you do?
- A. Create a Managed Instance Group with autoscaling
- B. Use Kubeflow Pipelines to train on a Google Kubernetes Engine cluster.
- C. Create a cluster on Dataproc for training
- D. Use Vertex Al Platform for distributed training
正解:D
解説:
AI platform also contains kubeflow pipelines. you don't need to set up infrastructure to use it. For D you need to set up a kubernetes cluster engine. The question asks us to minimize infrastructure overheard.
質問 # 46
A large company has developed a BI application that generates reports and dashboards using data collected from various operational metrics. The company wants to provide executives with an enhanced experience so they can use natural language to get data from the reports. The company wants the executives to be able ask questions using written and spoken interfaces.
Which combination of services can be used to build this conversational interface? (Choose three.)
- A. Amazon Connect
- B. Amazon Polly
- C. Amazon Transcribe
- D. Amazon Comprehend
- E. Alexa for Business
- F. Amazon Lex
正解:A、C、D
質問 # 47
You are working on a system log anomaly detection model for a cybersecurity organization. You have developed the model using TensorFlow, and you plan to use it for real-time prediction. You need to create a Dataflow pipeline to ingest data via Pub/Sub and write the results to BigQuery. You want to minimize the serving latency as much as possible. What should you do?
- A. Deploy the model to a Vertex AI endpoint, and invoke this endpoint in the Dataflow job.
- B. Deploy the model in a TFServing container on Google Kubernetes Engine, and invoke it in the Dataflow job.
- C. Load the model directly into the Dataflow job as a dependency, and use it for prediction.
- D. Containerize the model prediction logic in Cloud Run, which is invoked by Dataflow.
正解:D
解説:
Containerizing the model prediction logic in Cloud Run allows for easy and efficient deployment of the model, and allows it to be invoked by Dataflow. Cloud Run is a fully managed service that allows you to run stateless containers in a serverless environment. It automatically scales instances up and down based on the traffic, which can minimize the serving latency.
Additionally, Dataflow can easily invoke Cloud Run services via HTTP requests, making it simple to integrate into your pipeline. This allows the Dataflow pipeline to focus on data ingestion and processing, while the Cloud Run service handles the real-time predictions.
While it is possible to load the model directly into the Dataflow job as a dependency, this approach can increase the complexity of the pipeline and could lead to increased latency. Other options, such as deploying the model to a Vertex AI endpoint or a TFServing container on GKE, would also work but this option is the most optimal for minimizing the serving latency.
質問 # 48
A Data Scientist is developing a machine learning model to classify whether a financial transaction is fraudulent. The labeled data available for training consists of 100,000 non-fraudulent observations and 1,000 fraudulent observations.
The Data Scientist applies the XGBoost algorithm to the data, resulting in the following confusion matrix when the trained model is applied to a previously unseen validation dataset. The accuracy of the model is 99.1%, but the Data Scientist has been asked to reduce the number of false negatives.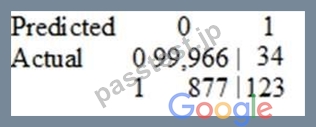
Which combination of steps should the Data Scientist take to reduce the number of false positive predictions by the model? (Choose two.)
- A. Change the XGBoost eval_metric parameter to optimize based on AUC instead of error.
- B. Increase the XGBoost scale_pos_weight parameter to adjust the balance of positive and negative weights.
- C. Change the XGBoost eval_metric parameter to optimize based on rmse instead of error.
- D. Decrease the XGBoost max_depth parameter because the model is currently overfitting the data.
- E. Increase the XGBoost max_depth parameter because the model is currently underfitting the data.
正解:A、D
質問 # 49
Your data science team needs to rapidly experiment with various features, model architectures, and hyperparameters. They need to track the accuracy metrics for various experiments and use an API to query the metrics over time. What should they use to track and report their experiments while minimizing manual effort?
- A. Use Al Platform Training to execute the experiments Write the accuracy metrics to Cloud Monitoring, and query the results using the Monitoring API.
- B. Use Al Platform Notebooks to execute the experiments. Collect the results in a shared Google Sheets file, and query the results using the Google Sheets API
- C. Use Al Platform Training to execute the experiments Write the accuracy metrics to BigQuery, and query the results using the BigQueryAPI.
- D. Use Kubeflow Pipelines to execute the experiments Export the metrics file, and query the results using the Kubeflow Pipelines API.
正解:D
質問 # 50
You are an ML engineer at a global car manufacturer. You need to build an ML model to predict car sales in different cities around the world. Which features or feature crosses should you use to train city-specific relationships between car type and number of sales?
- A. Two feature crosses as a element-wise product the first between binned latitude and one-hot encoded car type, and the second between binned longitude and one-hot encoded car type
- B. One feature obtained as an element-wise product between binned latitude, binned longitude, and one-hot encoded car type
- C. One feature obtained as an element-wise product between latitude, longitude, and car type
- D. Three individual features binned latitude, binned longitude, and one-hot encoded car type
正解:D
質問 # 51
You have trained a deep neural network model on Google Cloud. The model has low loss on the training data, but is performing worse on the validation dat a. You want the model to be resilient to overfitting. Which strategy should you use when retraining the model?
- A. Run a hyperparameter tuning job on Al Platform to optimize for the learning rate, and increase the number of neurons by a factor of 2.
- B. Run a hyperparameter tuning job on Al Platform to optimize for the L2 regularization and dropout parameters
- C. Apply a dropout parameter of 0 2, and decrease the learning rate by a factor of 10
- D. Apply a 12 regularization parameter of 0.4, and decrease the learning rate by a factor of 10.
正解:B
解説:
https://machinelearningmastery.com/introduction-to-regularization-to-reduce-overfitting-and-improve-generalization-error/
質問 # 52
A Machine Learning Specialist trained a regression model, but the first iteration needs optimizing. The Specialist needs to understand whether the model is more frequently overestimating or underestimating the target.
What option can the Specialist use to determine whether it is overestimating or underestimating the target value?
- A. Area under the curve
- B. Residual plots
- C. Confusion matrix
- D. Root Mean Square Error (RMSE)
正解:A
質問 # 53
You need to train a regression model based on a dataset containing 50,000 records that is stored in BigQuery. The data includes a total of 20 categorical and numerical features with a target variable that can include negative values. You need to minimize effort and training time while maximizing model performance. What approach should you take to train this regression model?
- A. Create a custom TensorFlow DNN model.
- B. Use AutoML Tables to train the model with RMSLE as the optimization objective
- C. Use AutoML Tables to train the model without early stopping.
- D. Use BQML XGBoost regression to train the model
正解:D
解説:
https://cloud.google.com/bigquery-ml/docs/introduction
質問 # 54
You work for a magazine distributor and need to build a model that predicts which customers will renew their subscriptions for the upcoming year. Using your company's historical data as your training set, you created a TensorFlow model and deployed it to AI Platform. You need to determine which customer attribute has the most predictive power for each prediction served by the model. What should you do?
- A. Use the AI Explanations feature on AI Platform. Submit each prediction request with the 'explain' keyword to retrieve feature attributions using the sampled Shapley method.
- B. Use the What-If tool in Google Cloud to determine how your model will perform when individual features are excluded. Rank the feature importance in order of those that caused the most significant performance drop when removed from the model.
- C. Use AI Platform notebooks to perform a Lasso regression analysis on your model, which will eliminate features that do not provide a strong signal.
- D. Stream prediction results to BigQuery. Use BigQuery's CORR(X1, X2) function to calculate the Pearson correlation coefficient between each feature and the target variable.
正解:B
質問 # 55
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this: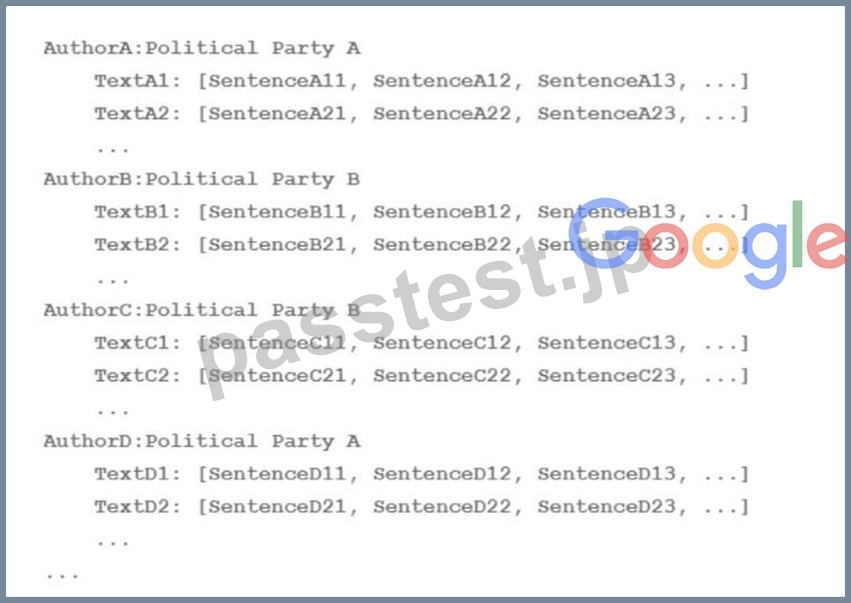
A)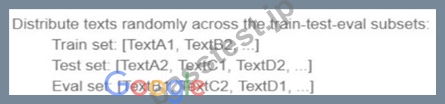
B)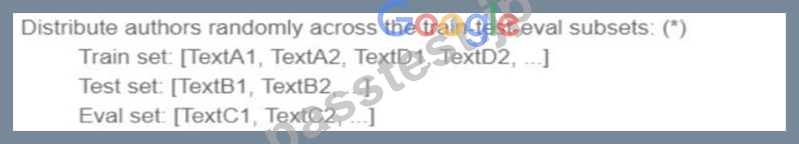
C)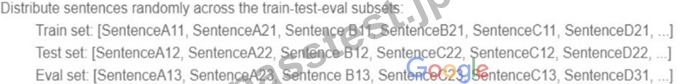
D)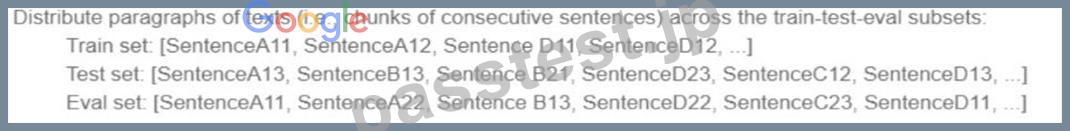
- A. Option A
- B. Option C
- C. Option D
- D. Option B
正解:C
質問 # 56
You were asked to investigate failures of a production line component based on sensor readings. After receiving the dataset, you discover that less than 1% of the readings are positive examples representing failure incidents. You have tried to train several classification models, but none of them converge. How should you resolve the class imbalance problem?
- A. Use the class distribution to generate 10% positive examples
- B. Use a convolutional neural network with max pooling and softmax activation
- C. Remove negative examples until the numbers of positive and negative examples are equal
- D. Downsample the data with upweighting to create a sample with 10% positive examples
正解:B
質問 # 57
A Machine Learning Specialist must build out a process to query a dataset on Amazon S3 using Amazon Athena. The dataset contains more than 800,000 records stored as plaintext CSV files. Each record contains
200 columns and is approximately 1.5 MB in size. Most queries will span 5 to 10 columns only.
How should the Machine Learning Specialist transform the dataset to minimize query runtime?
- A. Convert the records to JSON format.
- B. Convert the records to XML format.
- C. Convert the records to Apache Parquet format.
- D. Convert the records to GZIP CSV format.
正解:C
解説:
Using compressions will reduce the amount of data scanned by Amazon Athena, and also reduce your S3 bucket storage. It's a Win-Win for your AWS bill. Supported formats: GZIP, LZO, SNAPPY (Parquet) and ZLIB.
Reference: https://www.cloudforecast.io/blog/using-parquet-on-athena-to-save-money-on-aws/
質問 # 58
You work for a social media company. You need to detect whether posted images contain cars. Each training example is a member of exactly one class. You have trained an object detection neural network and deployed the model version to Al Platform Prediction for evaluation. Before deployment, you created an evaluation job and attached it to the Al Platform Prediction model version. You notice that the precision is lower than your business requirements allow. How should you adjust the model's final layer softmax threshold to increase precision?
- A. Decrease the number of false negatives
- B. Increase the number of false positives
- C. Increase the recall
- D. Decrease the recall.
正解:A
質問 # 59
......
2024年最新の実際にある検証済みのProfessional-Machine-Learning-Engineer問題集:https://www.passtest.jp/Google/Professional-Machine-Learning-Engineer-shiken.html
合格させるProfessional-Machine-Learning-Engineer試験で更新された150問題あります:https://drive.google.com/open?id=1TTpW9pJhHtz8RKb_vVVoYaHthInb74PX