

[2024年06月11日]Professional-Machine-Learning-Engineer試験問題集でリアル試験と100%同じ問題と解答
Professional-Machine-Learning-Engineerテストエンジン問題集トレーニングには271問あります
Google Professional Machine Learning Engineer Examは、機械学習エンジニアリングにおける個人の専門知識を検証するために設計された認定試験です。この試験の目的は、Google Cloud Platform Technologiesを使用して、高度にスケーラブルで堅牢で保守可能な機械学習モデルを作成および展開する候補者の能力を評価することを目的としています。この試験では、機械学習アーキテクチャの設計と実装、機械学習を使用したビジネス上の問題の解決、および機械学習ワークフローの最適化における候補者の習熟度もテストしています。
Google Professional Machine Learning Engineer認定は、機械学習の分野でのキャリアを促進しようとしている専門家にとって非常に価値のある資格です。認定は、候補者がGoogle Cloudの機械学習ツールとサービスを使用して、非常にスケーラブルで効率的な機械学習ソリューションを設計、構築、展開するために必要なスキルと専門知識を持っていることを示しています。この試験では、機械学習ソリューションを設計および実装する候補者の能力を評価する主要な機械学習の概念、パフォーマンスベースのタスク、ケーススタディに関する候補者の知識をテストします。
質問 # 160
A company is using Amazon Polly to translate plaintext documents to speech for automated company announcements. However, company acronyms are being mispronounced in the current documents.
How should a Machine Learning Specialist address this issue for future documents?
- A. Create an appropriate pronunciation lexicon.
- B. Use Amazon Lex to preprocess the text files for pronunciation
- C. Output speech marks to guide in pronunciation.
- D. Convert current documents to SSML with pronunciation tags.
正解:D
解説:
Explanation/Reference: https://docs.aws.amazon.com/polly/latest/dg/ssml.html
質問 # 161
You work for a company that is developing a new video streaming platform. You have been asked to create a recommendation system that will suggest the next video for a user to watch. After a review by an AI Ethics team, you are approved to start development. Each video asset in your company's catalog has useful metadata (e.g., content type, release date, country), but you do not have any historical user event data. How should you build the recommendation system for the first version of the product?
- A. Launch the product with machine learning. Generate embeddings for each video by training an autoencoder on the content metadata using TensorFlow. Cluster content based on the similarity of these embeddings, and then recommend videos from the same cluster.
- B. Launch the product without machine learning. Use simple heuristics based on content metadata to recommend similar videos to users, and start collecting user event data so you can develop a recommender model in the future.
- C. Launch the product without machine learning. Present videos to users alphabetically, and start collecting user event data so you can develop a recommender model in the future.
- D. Launch the product with machine learning. Use a publicly available dataset such as MovieLens to train a model using the Recommendations AI, and then apply this trained model to your data.
正解:B
解説:
The best option for building a recommendation system without any user event data is to use simple heuristics based on content metadata. This is a type of content-based filtering, which recommends items that are similar to the ones that the user has interacted with or selected, based on their attributes. For example, if a user selects a comedy movie from the US released in 2020, the system can recommend other comedy movies from the US released in 2020 or nearby years. This approach doesnot require any machine learning, but it can leverage the existing metadata of the videos to provide relevant recommendations. It also allows the system to start collecting user event data, such as views, likes, ratings, etc., which can be used to train a more sophisticated machine learning model in the future, such as a collaborative filtering model or a hybrid model that combines content and collaborative information. References:
* Recommendation Systems
* Content-Based Filtering
* Collaborative Filtering
* Hybrid Recommender Systems: A Systematic Literature Review
質問 # 162
You recently trained a XGBoost model that you plan to deploy to production for online inference Before sending a predict request to your model's binary you need to perform a simple data preprocessing step This step exposes a REST API that accepts requests in your internal VPC Service Controls and returns predictions You want to configure this preprocessing step while minimizing cost and effort What should you do?
- A. Build a Flask-based app. package the app and a pickled model in a custom container image, and deploy the model to Vertex Al Endpoints.
- B. Store a pickled model in Cloud Storage Build a Flask-based app packages the app in a custom container image, and deploy the model to Vertex Al Endpoints.
- C. Build a custom predictor class based on XGBoost Predictor from the Vertex Al SDK and package the handler in a custom container image based on a Vertex built-in container image Store a pickled model in Cloud Storage and deploy the model to Vertex Al Endpoints.
- D. Build a custom predictor class based on XGBoost Predictor from the Vertex Al SDK. package it and a pickled model in a custom container image based on a Vertex built-in image, and deploy the model to Vertex Al Endpoints.
正解:D
質問 # 163
A Machine Learning Specialist is packaging a custom ResNet model into a Docker container so the company can leverage Amazon SageMaker for training. The Specialist is using Amazon EC2 P3 instances to train the model and needs to properly configure the Docker container to leverage the NVIDIA GPUs.
What does the Specialist need to do?
- A. Build the Docker container to be NVIDIA-Docker compatible.
- B. Set the GPU flag in the Amazon SageMaker CreateTrainingJob request body.
- C. Organize the Docker container's file structure to execute on GPU instances.
- D. Bundle the NVIDIA drivers with the Docker image.
正解:D
質問 # 164
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?
- A.
- B.
- C.
- D.

正解:D
解説:
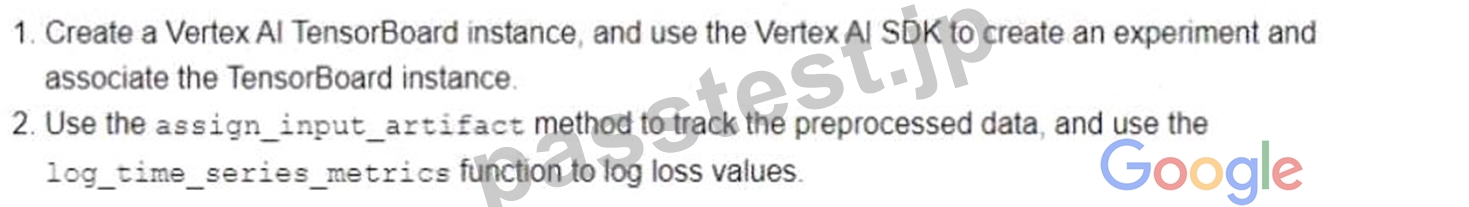
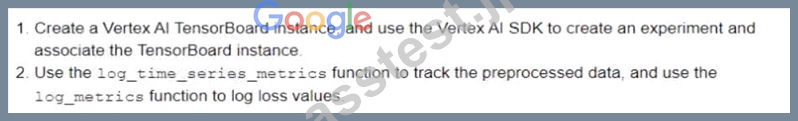
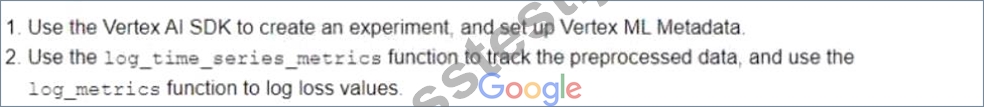
The option A is the most suitable solution for logging data and tracking artifacts from each run of a model development experiment in a Vertex AI Workbench notebook. Vertex AI Workbench is a service that allows you to create and run interactive notebooks on Google Cloud. You can use Vertex AI Workbench to experiment with different preprocessing and modeling approaches for your time series prediction problem.
You can also use the Vertex AI TensorBoard instance and the Vertex AI SDK to create an experiment and associate the TensorBoard instance. TensorBoard is a tool that allows you to visualize and monitor the metrics and artifacts of your ML experiments. You can use the Vertex AI SDK to create an experiment object, which is a logical grouping of runs that share a common objective. You can also use the Vertex AI SDK to associate the experiment object with a TensorBoard instance, which is a managed service that hosts a TensorBoard web app. By using the Vertex AI TensorBoard instance and the Vertex AI SDK, you can easily set up and manage your experiments, and access the TensorBoard web app from the Vertex AI console. You can also use the log_time_series_metrics function and the log_metrics function to log data and track artifacts from each run.
The log_time_series_metrics function is a function that allows you to log the time series data, such as the multivariate time series and the labels, to the TensorBoard instance. The log_metrics function is a function that allows you to log the scalar metrics, such as the loss values, to the TensorBoard instance. By using these functions, you can record the data and artifacts from each run of your experiment, and compare them in the TensorBoard web app. You can also use the TensorBoard web app to visualize the data and artifacts, such as the time series plots, the scalar charts, the histograms, and the distributions. By using the Vertex AI TensorBoard instance, the Vertex AI SDK, and the log functions, you can log data and track artifacts from each run of your experiment in a Vertex AI Workbench notebook. References:
* Vertex AI Workbench documentation
* Vertex AI TensorBoard documentation
* Vertex AI SDK documentation
* log_time_series_metrics function documentation
* log_metrics function documentation
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
質問 # 165
You work for the AI team of an automobile company, and you are developing a visual defect detection model using TensorFlow and Keras. To improve your model performance, you want to incorporate some image augmentation functions such as translation, cropping, and contrast tweaking. You randomly apply these functions to each training batch. You want to optimize your data processing pipeline for run time and compute resources utilization. What should you do?
- A. Embed the augmentation functions dynamically in the tf.Data pipeline.
- B. Embed the augmentation functions dynamically as part of Keras generators.
- C. Use Dataflow to create all possible augmentations, and store them as TFRecords.
- D. Use Dataflow to create the augmentations dynamically per training run, and stage them as TFRecords.
正解:C
質問 # 166
A Machine Learning Specialist is preparing data for training on Amazon SageMaker. The Specialist is using one of the SageMaker built-in algorithms for the training. The dataset is stored in .CSV format and is transformed into a numpy.array, which appears to be negatively affecting the speed of the training.
What should the Specialist do to optimize the data for training on SageMaker?
- A. Use AWS Glue to compress the data into the Apache Parquet format.
- B. Use the SageMaker batch transform feature to transform the training data into a DataFrame.
- C. Transform the dataset into the RecordIO protobufformat.
- D. Use the SageMaker hyperparameter optimization feature to automatically optimize the data.
正解:C
質問 # 167
Your data science team is training a PyTorch model for image classification based on a pre-trained RestNet model. You need to perform hyperparameter tuning to optimize for several parameters. What should you do?
- A. Run a hyperparameter tuning job on AI Platform using custom containers.
- B. Convert the model to a Keras model, and run a Keras Tuner job.
- C. Convert the model to a TensorFlow model, and run a hyperparameter tuning job on AI Platform.
- D. Create a Kuberflow Pipelines instance, and run a hyperparameter tuning job on Katib.
正解:D
質問 # 168
You work for a company that provides an anti-spam service that flags and hides spam posts on social media platforms. Your company currently uses a list of 200,000 keywords to identify suspected spam posts. If a post contains more than a few of these keywords, the post is identified as spam. You want to start using machine learning to flag spam posts for human review. What is the main advantage of implementing machine learning for this business case?
- A. New problematic phrases can be identified in spam posts.
- B. Posts can be compared to the keyword list much more quickly.
- C. A much longer keyword list can be used to flag spam posts.
- D. Spam posts can be flagged using far fewer keywords.
正解:A
解説:
The main advantage of implementing machine learning for this business case is that new problematic phrases can be identified in spam posts. This is because machine learning can learn from the data and the feedback, and adapt to the changing patterns and trends of spam posts. Machine learning can also capture the semantic and contextual meaning of the posts, and not just rely on the presence or absence of keywords. By using machine learning, you can improve the accuracy and coverage of your anti-spam service, and detect new and emerging types of spam posts that may not be captured by the keyword list.
The other options are not advantages of implementing machine learning for this business case for the following reasons:
* A. Posts can be compared to the keyword list much more quickly is not an advantage, as it does not improve the quality or effectiveness of the anti-spam service. It only improves the efficiency of the service, which is not the primary objective. Moreover, machine learning may not necessarily be faster than the keyword list, depending on the complexity and size of the model and the data.
* C. A much longer keyword list can be used to flag spam posts is not an advantage, as it does not address the limitations or challenges of the keyword list approach. It only increases the size and complexity of the keyword list, which can make it harder to maintain and update. Moreover, a longer keyword list may not improve the accuracy or coverage of the anti-spam service, as it may introduce more false positives or false negatives, or miss new and emerging types of spam posts.
* D. Spam posts can be flagged using far fewer keywords is not an advantage, as it does not reflect the capabilities or benefits of machine learning. It only reduces the size and complexity of the keyword list,
* which can make it easier to maintain and update. However, using fewer keywords may not improve the accuracy or coverage of the anti-spam service, as it may lose some information or meaning of the posts, or miss some types of spam posts.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Machine Learning for Spam Detection
* Spam Detection Using Machine Learning
質問 # 169
You are working on a binary classification ML algorithm that detects whether an image of a classified scanned document contains a company's logo. In the dataset, 96% of examples don't have the logo, so the dataset is very skewed. Which metrics would give you the most confidence in your model?
- A. F1 score
- B. RMSE
- C. F-score where precision is weighed more than recall
- D. F-score where recall is weighed more than precision
正解:D
解説:
* Option A is correct because using F-score where recall is weighed more than precision is a suitable metric for binary classification with imbalanced data. F-score is a harmonic mean of precision and recall, which are two metrics that measure the accuracy and completeness of the positive class1. Precision is the fraction of true positives among all predicted positives, while recall is the fraction of true positives among all actual positives1. When the data is imbalanced, the positive class is the minority class, which is usually the class of interest. For example, in this case, the positive class is the images that contain the company's logo, which are rare but important to detect. By weighing recall more than precision, we can emphasize the importance of finding all the positive examples, even if some false positives are included2.
* Option B is incorrect because using RMSE (root mean squared error) is not a valid metric for binary classification with imbalanced data. RMSE is a metric that measures the average magnitude of the errors between the predicted and actual values3. RMSE is suitable for regression problems, where the target variable is continuous, not for classification problems, where the target variable is discrete4.
* Option C is incorrect because using F1 score is not the best metric for binary classification with imbalanced data. F1 score is a special case of F-score where precision and recall are equally weighted1. F1 score is suitable for balanced data, where the positive and negative classes are equally important and frequent5. However, for imbalanced data, the positive class is more important and less frequent than the negative class, so F1 score may not reflect the performance of the model well2.
* Option D is incorrect because using F-score where precision is weighed more than recall is not a good metric for binary classification with imbalanced data. By weighing precision more than recall, we can
* emphasize the importance of minimizing the false positives, even if some true positives are missed2. However, for imbalanced data, the true positives are more important and less frequent than the false positives, so this metric may not reflect the performance of the model well2.
References:
* Precision, recall, and F-measure
* F-score for imbalanced data
* RMSE
* Regression vs classification
* F1 score
* [Imbalanced classification]
* [Binary classification]
質問 # 170
You work for a gaming company that develops massively multiplayer online (MMO) games. You built a TensorFlow model that predicts whether players will make in-app purchases of more than $10 in the next two weeks. The model's predictions will be used to adapt each user's game experience. User data is stored in BigQuery. How should you serve your model while optimizing cost, user experience, and ease of management?
- A. Embed the model in the mobile application. Make predictions after every in-app purchase event is published in Pub/Sub, and push the data to Cloud SQL.
- B. Deploy the model to Vertex AI Prediction. Make predictions using batch reading data from Cloud Bigtable, and push the data to Cloud SQL.
- C. Import the model into BigQuery ML. Make predictions using batch reading data from BigQuery, and push the data to Cloud SQL
- D. Embed the model in the streaming Dataflow pipeline. Make predictions after every in-app purchase event is published in Pub/Sub, and push the data to Cloud SQL.
正解:B
解説:
The best option to serve the model while optimizing cost, user experience, and ease of management is to deploy the model to Vertex AI Prediction, which is a managed service that can scale up or down according to the demand and provide low latency and high availability. Vertex AI Prediction can also handle TensorFlow models natively, without requiring any additional steps or conversions. By using batch prediction, the model can process large volumes of data efficiently and periodically, without affecting the user experience. The data can be read from Cloud Bigtable, which is a scalable and performant NoSQL database that can store user data in a flexible schema. The predictions can then be pushed to Cloud SQL, which is a fully managed relational database that can store the predictions in a structured format and enable easy querying and analysis. This option also simplifies the management of the model and the data, as it leverages the existing Google Cloud services and does not require any additional infrastructure or code.
The other options are not optimal for the following reasons:
* A. Importing the model into BigQuery ML is not a good option, as it requires converting the TensorFlow model into a format that BigQuery ML can understand, which can introduce errors and reduce the performance. Moreover, BigQuery ML is not designed for serving real-time predictions, but rather for training and evaluating models using SQL queries. Reading and writing data from BigQuery and Cloud SQL can also incur additional costs and latency, as they are both relational databases that require schema definition and data transformation.
* C. Embedding the model in the mobile application is not a good option, as it increases the size and
* complexity of the application, and requires updating the application every time the model changes.
Moreover, it exposes the model to the users, which can pose security and privacy risks, as well as potential misuse or abuse. Additionally, it does not leverage the benefits of the cloud, such as scalability, reliability, and performance.
* D. Embedding the model in the streaming Dataflow pipeline is not a good option, as it requires building and maintaining a custom pipeline that can handle the model inference and data processing. This can increase the development and operational costs and complexity, as well as the potential for errors and failures. Moreover, it does not take advantage of the batch prediction feature of Vertex AI Prediction, which can optimize the resource utilization and cost efficiency.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Vertex AI Prediction documentation
* Cloud Bigtable documentation
* Cloud SQL documentation
質問 # 171
You are training an ML model using data stored in BigQuery that contains several values that are considered Personally Identifiable Information (Pll). You need to reduce the sensitivity of the dataset before training your model. Every column is critical to your model. How should you proceed?
- A. Use the Cloud Data Loss Prevention (DLP) API to scan for sensitive data, and use Dataflow to replace all sensitive data by using the encryption algorithm AES-256 with a salt.
- B. Before training, use BigQuery to select only the columns that do not contain sensitive data Create an authorized view of the data so that sensitive values cannot be accessed by unauthorized individuals.
- C. Using Dataflow, ingest the columns with sensitive data from BigQuery, and then randomize the values in each sensitive column.
- D. Use the Cloud Data Loss Prevention (DLP) API to scan for sensitive data, and use Dataflow with the DLP API to encrypt sensitive values with Format Preserving Encryption
正解:B
解説:
This approach would allow you to keep the critical columns of data while reducing the sensitivity of the dataset by removing the personally identifiable information (PII) before training the model. By creating an authorized view of the data, you can ensure that sensitive values cannot be accessed by unauthorized individuals.
質問 # 172
You work with a data engineering team that has developed a pipeline to clean your dataset and save it in a Cloud Storage bucket. You have created an ML model and want to use the data to refresh your model as soon as new data is available. As part of your CI/CD workflow, you want to automatically run a Kubeflow Pipelines training job on Google Kubernetes Engine (GKE). How should you architect this workflow?
- A. Use Cloud Scheduler to schedule jobs at a regular interval. For the first step of the job. check the timestamp of objects in your Cloud Storage bucket If there are no new files since the last run, abort the job.
- B. Configure your pipeline with Dataflow, which saves the files in Cloud Storage After the file is saved, start the training job on a GKE cluster
- C. Use App Engine to create a lightweight python client that continuously polls Cloud Storage for new files As soon as a file arrives, initiate the training job
- D. Configure a Cloud Storage trigger to send a message to a Pub/Sub topic when a new file is available in a storage bucket. Use a Pub/Sub-triggered Cloud Function to start the training job on a GKE cluster
正解:B
質問 # 173
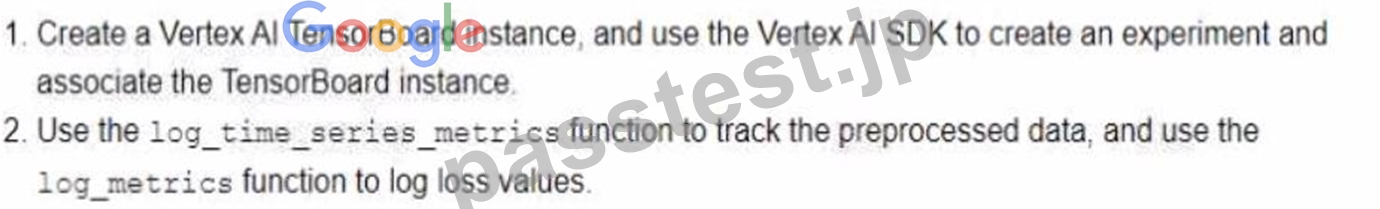
You are developing a model to predict whether a failure will occur in a critical machine part. You have a dataset consisting of a multivariate time series and labels indicating whether the machine part failed You recently started experimenting with a few different preprocessing and modeling approaches in a Vertex Al Workbench notebook. You want to log data and track artifacts from each run. How should you set up your experiments?
- A.
- B.
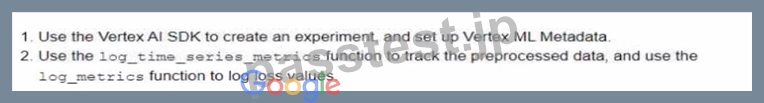
- C.
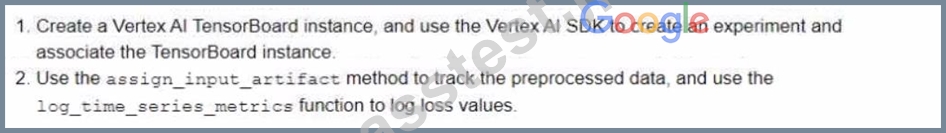
- D.
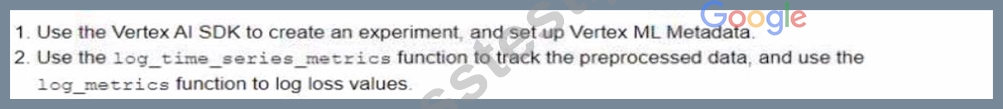
正解:D
質問 # 174
You are working on a binary classification ML algorithm that detects whether an image of a classified scanned document contains a company's logo. In the dataset, 96% of examples don't have the logo, so the dataset is very skewed. Which metrics would give you the most confidence in your model?
- A. F1 score
- B. RMSE
- C. F-score where precision is weighed more than recall
- D. F-score where recall is weighed more than precision
正解:D
解説:
* Option A is correct because using F-score where recall is weighed more than precision is a suitable metric for binary classification with imbalanced data. F-score is a harmonic mean of precision and recall, which are two metrics that measure the accuracy and completeness of the positive class1. Precision is the fraction of true positives among all predicted positives, while recall is the fraction of true positives among all actual positives1. When the data is imbalanced, the positive class is the minority class, which is usually the class of interest. For example, in this case, the positive class is the images that contain the company's logo, which are rare but important to detect. By weighing recall more than precision, we can emphasize the importance of finding all the positive examples, even if some false positives are included2.
* Option B is incorrect because using RMSE (root mean squared error) is not a valid metric for binary classification with imbalanced data. RMSE is a metric that measures the average magnitude of the errors between the predicted and actual values3. RMSE is suitable for regression problems, where the target variable is continuous, not for classification problems, where the target variable is discrete4.
* Option C is incorrect because using F1 score is not the best metric for binary classification with imbalanced data. F1 score is a special case of F-score where precision and recall are equally weighted1. F1 score is suitable for balanced data, where the positive and negative classes are equally important and frequent5. However, for imbalanced data, the positive class is more important and less frequent than the negative class, so F1 score may not reflect the performance of the model well2.
* Option D is incorrect because using F-score where precision is weighed more than recall is not a good metric for binary classification with imbalanced data. By weighing precision more than recall, we can emphasize the importance of minimizing the false positives, even if some true positives are missed2. However, for imbalanced data, the true positives are more important and less frequent than the false positives, so this metric may not reflect the performance of the model well2.
References:
* Precision, recall, and F-measure
* F-score for imbalanced data
* RMSE
* Regression vs classification
* F1 score
* [Imbalanced classification]
* [Binary classification]
質問 # 175
You recently trained a XGBoost model that you plan to deploy to production for online inference Before sending a predict request to your model's binary you need to perform a simple data preprocessing step This step exposes a REST API that accepts requests in your internal VPC Service Controls and returns predictions You want to configure this preprocessing step while minimizing cost and effort What should you do?
- A. Build a Flask-based app. package the app and a pickled model in a custom container image, and deploy the model to Vertex Al Endpoints.
- B. Build a custom predictor class based on XGBoost Predictor from the Vertex Al SDK. package it and a pickled model in a custom container image based on a Vertex built-in image, and deploy the model to Vertex Al Endpoints.
- C. Store a pickled model in Cloud Storage Build a Flask-based app packages the app in a custom container image, and deploy the model to Vertex Al Endpoints.
- D. Build a custom predictor class based on XGBoost Predictor from the Vertex Al SDK and package the handler in a custom container image based on a Vertex built-in container image Store a pickled model in Cloud Storage and deploy the model to Vertex Al Endpoints.
正解:D
解説:
* Option A is not the best answer because it requires storing the pickled model in Cloud Storage, which may incur additional cost and latency for loading the model. It also requires building a Flask-based app, which may not be necessary for a simple data preprocessing step.
* Option B is not the best answer because it requires building a Flask-based app, which may not be necessary for a simple data preprocessing step. It also requires packaging the app andthe pickled model in a custom container image, which may increase the size and complexity of the image.
* Option C is not the best answer because it requires packaging the pickled model in a custom container image, which may increase the size and complexity of the image. It also does not leverage the Vertex built-in container image, which may provide some optimizations and integrations for XGBoost models.
* Option D is the best answer because it leverages the Vertex built-in container image, which may provide some optimizations and integrations for XGBoost models. It also allows storing the pickled model in Cloud Storage, which may reduce the size and complexity of the image. It also allows building a custom predictor class based on XGBoost Predictor from the Vertex AI SDK, which may simplify the data preprocessing step and the prediction logic.
質問 # 176
You developed a Vertex Al ML pipeline that consists of preprocessing and training steps and each set of steps runs on a separate custom Docker image Your organization uses GitHub and GitHub Actions as CI/CD to run unit and integration tests You need to automate the model retraining workflow so that it can be initiated both manually and when a new version of the code is merged in the main branch You want to minimize the steps required to build the workflow while also allowing for maximum flexibility How should you configure the CI/CD workflow?
- A. Trigger GitHub Actions to run the tests launch a Cloud Build workflow to build custom Dicker images, push the images to Artifact Registry, and launch the pipeline in Vertex Al Pipelines.
- B. Trigger GitHub Actions to run the tests build custom Docker images push the images to Artifact Registry, and launch the pipeline in Vertex Al Pipelines.
- C. Trigger GitHub Actions to run the tests launch a job on Cloud Run to build custom Docker images push the images to Artifact Registry and launch the pipeline in Vertex Al Pipelines.
- D. Trigger a Cloud Build workflow to run tests build custom Docker images, push the images to Artifact Registry and launch the pipeline in Vertex Al Pipelines.
正解:B
質問 # 177
You work for an online grocery store. You recently developed a custom ML model that recommends a recipe when a user arrives at the website. You chose the machine type on the Vertex Al endpoint to optimize costs by using the queries per second (QPS) that the model can serve, and you deployed it on a single machine with 8 vCPUs and no accelerators.
A holiday season is approaching and you anticipate four times more traffic during this time than the typical daily traffic You need to ensure that the model can scale efficiently to the increased demand. What should you do?
- A. 1, Maintain the same machine type on the endpoint.
2 Set up a monitoring job and an alert for CPU usage
3 If you receive an alert add a compute node to the endpoint - B. 1 Maintain the same machine type on the endpoint Configure the endpoint to enable autoscalling based on vCPU usage.
2 Set up a monitoring job and an alert for CPU usage
3 If you receive an alert investigate the cause - C. 1 Change the machine type on the endpoint to have 32 vCPUs
2. Set up a monitoring job and an alert for CPU usage
3 If you receive an alert, scale the vCPUs further as needed - D. 1 Change the machine type on the endpoint to have a GPU_ Configure the endpoint to enable autoscaling based on the GPU usage.
2 Set up a monitoring job and an alert for GPU usage.
3 If you receive an alert investigate the cause.
正解:B
質問 # 178
......
Professional-Machine-Learning-Engineer練習テストPDF試験材料:https://www.passtest.jp/Google/Professional-Machine-Learning-Engineer-shiken.html
Professional-Machine-Learning-Engineer問題で一発合格させる問題集にはGoogle Cloud Certified認定問題を使おう:https://drive.google.com/open?id=1TTpW9pJhHtz8RKb_vVVoYaHthInb74PX